Blog · · By Dhrumil Barot, Founder
GPT-5.2 Codex Pricing vs GPT-5.3-Codex and GPT-6.1 Sol
GPT-5.2-Codex cost $1.75 input and $14 output per 1M tokens and was shut down on 2026-07-23. Here is what 5.3-Codex and GPT-6.1 Sol cost per task.
TL;DR: GPT-5.2-Codex was priced at $1.75 per 1M input tokens, $0.175 cached and $14.00 output, and OpenAI shut it down on 2026-07-23. GPT-5.3-Codex has the identical price but is deprecated and leaves the API on 2027-04-01. On our editable agent-task model, gpt-6.1-sol costs $0.242 per task against $0.292 for GPT-5.3-Codex, 17% less.
GPT 5.2 Codex pricing was $1.75 per 1M input tokens, $0.175 per 1M cached input tokens and $14.00 per 1M output tokens on OpenAI's API (prices verified 2026-11-06 on the GPT-5.2-Codex model page). That price no longer buys anything: the OpenAI deprecations page lists gpt-5.2-codex as shut down on July 23, 2026, with gpt-5.6-sol as the substitute. GPT-5.3-Codex is still callable at the same $1.75 / $14.00, but it was deprecated on 2026-10-01 and is removed on April 1, 2027, with gpt-6-sol as the recommended replacement. If you are pricing a Codex workload today, the real choice is GPT-5.3-Codex for five more months or a GPT-6 Sol model now.
GPT-5.2-Codex vs GPT-5.3-Codex vs GPT-6.1 Sol: comparison table
Prices are USD per 1M tokens, Standard tier, verified 2026-11-06 on the OpenAI pricing page and each model page.
| Criterion | gpt-5.2-codex | gpt-5.3-codex | gpt-6.1-sol | gpt-6-sol |
|---|---|---|---|---|
| Status | Shut down 2026-07-23 | Deprecated, removed 2027-04-01 | Current | Current |
| Input | $1.75 | $1.75 | $2.00 | $2.00 |
| Cached input | $0.175 | $0.175 | $0.10 | $0.20 |
| Output | $14.00 | $14.00 | $10.00 | $10.00 |
| Cache write (30 min) | not listed | not listed | $2.50 | $2.50 |
| Fast tier (in / out) | n/a | $3.50 / $28.00 | $4.00 / $20.00 | not checked |
| Context window | 400,000 | 400,000 | 1,050,000 | 1,050,000 |
| Max output | 128,000 | 128,000 | 128,000 | 128,000 |
| Knowledge cutoff | 2025-08-31 | 2025-08-31 | 2026-04-30 | 2026-04-20 |
| Cost per agent task (model below) | $0.292 | $0.292 | $0.242 | $0.259 |
How much did GPT-5.2-Codex cost per 1M tokens?
GPT-5.2-Codex cost $1.75 per 1M input tokens, $0.175 per 1M cached input tokens and $14.00 per 1M output tokens. Cached input was 10% of the input rate. Reasoning tokens, which the model generates at the low, medium, high and xhigh effort settings, are billed as output, so the $14.00 line dominates most coding bills.
It was a step up from its predecessor: the model page's quick comparison lists gpt-5.1-codex at $1.25 input, so 5.2 raised input by 40%. Both shut down on the same day, 2026-07-23, in the batch OpenAI announced on 2026-04-22.
Calls to gpt-5.2-codex now fail. If an old config, a CI job or a third-party tool still pins that ID, that is the first thing to fix.
Is GPT-5.3-Codex available in the API, and at what price?
Yes, GPT-5.3-Codex is available in the API today at $1.75 input, $0.175 cached input and $14.00 output per 1M tokens, the same as 5.2. It is listed under "Specialized models" on the pricing page with a Fast tier at exactly double: $3.50 / $0.35 / $28.00. (OpenAI renamed Priority processing to Fast mode on 2026-07-30.)
The catch is the clock. The 2026-10-01 deprecation notice removes gpt-5.3-codex on April 1, 2027 and names gpt-6-sol as the replacement. OpenAI's policy gives Codex variants at least 3 months' notice versus 6 for generally available models, so specialized variants are the shorter-lived bet by design.
Both Codex models share the same spec: a 400,000-token context window, 128,000 max output tokens, an August 31, 2025 knowledge cutoff, text and image input, and the Chat Completions, Responses and Batch endpoints.
What does a typical coding task cost on each?
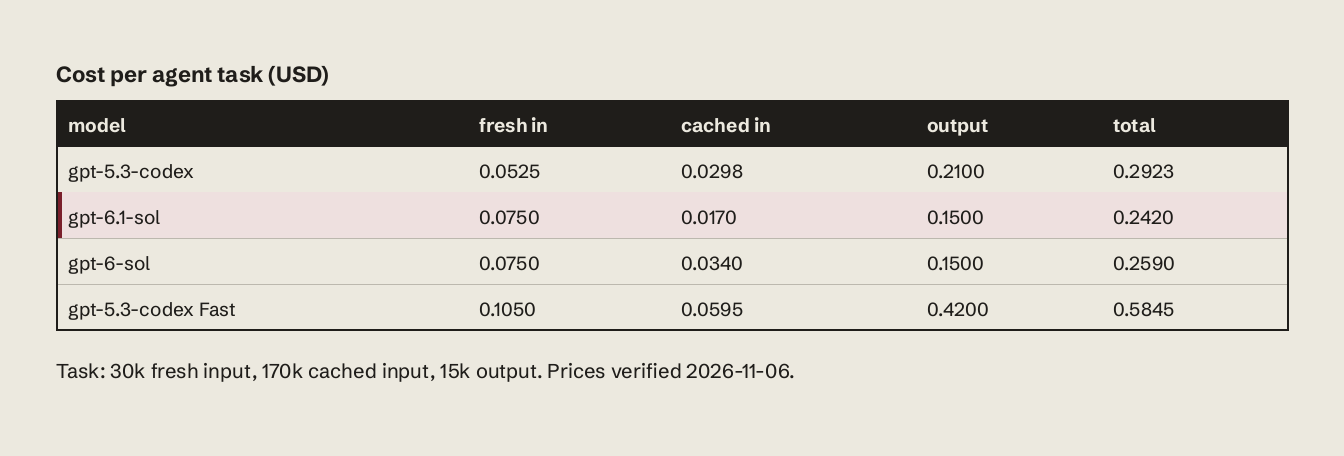
A typical agentic coding task costs $0.292 on GPT-5.3-Codex (and cost the same on 5.2) and $0.242 on gpt-6.1-sol under the workload below. Agent loops resend the repository context every turn, so most input is cached; we covered why in cache reads dominate agent costs.
Assumptions (edit them for your own runs):
| Assumption | Value | Why |
|---|---|---|
| Fresh input per task | 30,000 tokens | new files, tool results, diffs |
| Cached input per task | 170,000 tokens | system prompt and repo context resent each turn |
| Output per task, incl. reasoning | 15,000 tokens | edits plus reasoning at medium effort |
| GPT-6 fresh input billing | 30-minute cache write ($2.50) | conservative: assumes every new token is written to cache |
The arithmetic for GPT-5.3-Codex: 30,000 x $1.75/1M = $0.0525, plus 170,000 x $0.175/1M = $0.02975, plus 15,000 x $14.00/1M = $0.21. Total $0.29225, or $292.25 per 1,000 tasks.
For gpt-6.1-sol: 30,000 x $2.50/1M = $0.075, plus 170,000 x $0.10/1M = $0.017, plus 15,000 x $10.00/1M = $0.15. Total $0.242, or $242.00 per 1,000 tasks, 17.2% less. If your fresh tokens bill at the plain $2.00 input rate instead of the write rate, it drops to $0.227.
For gpt-6-sol the cached rate is $0.20, so cached input costs $0.034 and the total is $0.259 per task. Running GPT-5.3-Codex on the Fast tier doubles every line to $0.5845.
To rerun this with your own token counts, plug them into the LLM cost calculator.
One caveat we cannot price: different models use different token counts for the same task. A model that needs fewer turns or less reasoning wins even at a higher rate. Measure tokens per completed task on your own repo before you trust any per-token table, including ours.
When does GPT-5.3-Codex still cost less?
GPT-5.3-Codex is cheaper on input-heavy, uncached work, because its $1.75 input rate is below Sol's $2.00. Take a one-shot review of a large diff: 400,000 uncached input tokens and 5,000 output.
| Workload | gpt-5.3-codex | gpt-6.1-sol | Difference |
|---|---|---|---|
| Agent task (cached, above) | $0.292 | $0.242 | Sol 17.2% cheaper |
| Output-heavy: 50k in, 40k out, no cache | $0.648 | $0.500 | Sol 22.8% cheaper |
| Input-heavy: 400k in, 5k out, no cache | $0.770 | $0.850 | Codex 10.4% cheaper |
The output-heavy row: 50,000 x $1.75/1M + 40,000 x $14.00/1M = $0.0875 + $0.56 = $0.6475 versus $0.10 + $0.40 = $0.50. The input-heavy row: $0.70 + $0.07 = $0.77 versus $0.80 + $0.05 = $0.85.
That 10% edge expires on 2027-04-01, so it only matters if migration work costs more than five months of savings.
Which Codex model should I use?
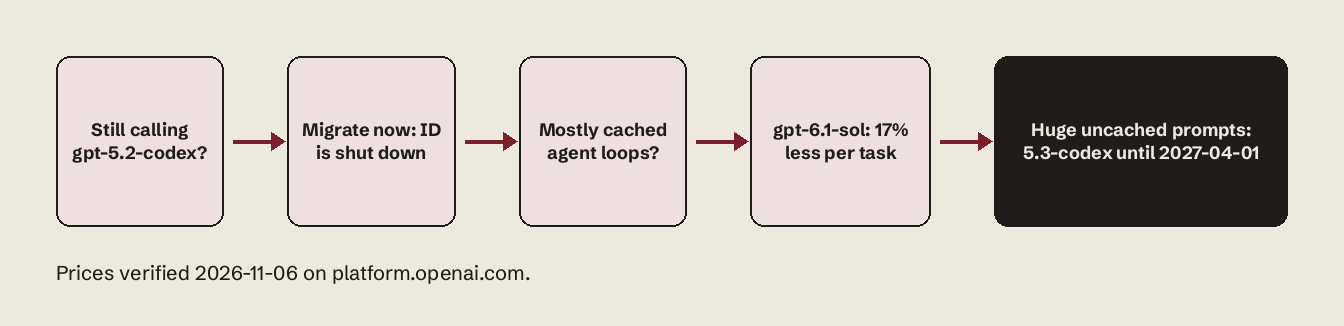
Use gpt-6.1-sol for new agentic coding work, keep GPT-5.3-Codex only where an existing pipeline is tuned to it, and remove every gpt-5.2-codex reference now.
Choose gpt-6.1-sol if your agent loop reuses context (cached input at $0.10, 5% of input), output and reasoning are a large share of the bill ($10.00 versus $14.00), or you need more than 400,000 tokens of context (1,050,000). Its knowledge cutoff is also eight months newer, which matters for recent library versions. Inside Codex and ChatGPT Work it defaults to a 500K context.
Choose gpt-5.3-codex if your prompts are large and uncached, your evals are pinned to its behaviour, and you will finish migrating before April 2027.
Choose gpt-6-sol if you want OpenAI's named replacement for 5.3-Codex. On price alone, gpt-6.1-sol beats it on cached input ($0.10 vs $0.20) at the same input and output rates.
Offline jobs, such as overnight test generation, can go to Batch: gpt-6.1-sol Batch is $1.00 input, $0.05 cached and $5.00 output, half of Standard. Data-residency endpoints add 10% for models released on or after 2026-03-05.
A forced migration like this one is the best moment to stop hardcoding a single model ID. Vynaris gives you one OpenAI-compatible endpoint across providers, so the next shutdown is a config change, not a code change; see the models we route to. If you only need OpenAI, the DIY path works: put the model ID in config and alert on deprecation emails.
For the full OpenAI price list, see our OpenAI API pricing guide, and for what happened to the GPT-5.6 tiers after their promo, GPT-5.6 Sol, Terra and Luna prices.
FAQ
Is GPT-5.2-Codex still available?
No. OpenAI shut down gpt-5.2-codex on July 23, 2026 and lists gpt-5.6-sol as its substitute. The model page now carries a "Shut down" label.
Is GPT-5.3-Codex more expensive than GPT-5.2-Codex?
No. Both are $1.75 input, $0.175 cached input and $14.00 output per 1M tokens. The difference was capability, not price.
When will GPT-5.3-Codex be removed?
April 1, 2027. OpenAI announced the deprecation on October 1, 2026 and recommends gpt-6-sol as the replacement.
Do reasoning tokens count as output for Codex models?
Yes. Reasoning tokens are billed at the output rate, $14.00 per 1M on GPT-5.3-Codex, so higher reasoning effort raises cost even when the visible answer is short.
What is the GPT-5.3-Codex Fast tier price?
$3.50 input, $0.35 cached input and $28.00 output per 1M tokens, double the Standard tier. Fast was called Priority processing until July 30, 2026.
What is the context window of GPT-5.3-Codex?
400,000 tokens, with up to 128,000 output tokens. gpt-6.1-sol raises the context window to 1,050,000 tokens with the same output cap.