---
title: "HTML-to-schema extraction cost: $1.11 per 1,000 pages after stripping boilerplate"
description: "Stripping HTML boilerplate cuts input 75.9% and lowers LLM extraction to $1.11-$17.76 per 1,000 pages. Prices verified 2026-08-05."
canonical: https://vynaris.com/blog/web-data-extraction-llm-html-to-schema-cost-per-1k-pages-playbook
author: "Dhrumil Barot"
author_bio: "Dhrumil is an AI inference and LLM infrastructure expert. Dhrumil built Vynaris to make model access, routing and pricing simple and transparent for developers."
published: 2026-08-05
updated: 2026-08-22
---
# HTML-to-schema extraction cost: $1.11 per 1,000 pages after stripping boilerplate
Published 2026-08-05 · Updated 2026-08-22 · By [Dhrumil Barot](https://vynaris.com/about#founder), Founder
Stripping HTML boilerplate cuts input 75.9% and lowers LLM extraction to $1.11-$17.76 per 1,000 pages. Prices verified 2026-08-05.
An LLM pipeline can turn 1,000 web pages into schema-valid JSON for $1.11 on deepseek-v4-flash or $17.76 on Claude Sonnet 5. The first cost lever is not the model. Removing navigation, scripts, styles and repeated chrome cuts billed input by 75.9% and saves 69.6% to 74.3%. Prices verified 2026-08-05.
## TL;DR
- The editable workload starts with 25,000 raw HTML tokens per page. Deterministic cleanup leaves 6,000 content tokens and the model emits 300 JSON tokens.
- A 15% verification sample and a 5% expected schema-drift retry bring the clean pipeline to 7.245M [input tokens](https://vynaris.com/glossary/category/cost-and-finops#input-token-cost) and 327,000 [output tokens](https://vynaris.com/glossary/category/cost-and-finops#output-token-cost) per 1,000 pages.
- The clean bill ranges from $1.1059 on deepseek-v4-flash to $17.7600 on Claude Sonnet 5, a 16.1x model spread.
- Sending raw HTML instead costs $4.2979 to $63.3600. Preprocessing saves more than most model swaps because page chrome is unique billed input, not a useful quality signal.
- Routing DeepSeek extraction to Sonnet verification costs $2.9802, 83.2% below all-Sonnet. Use it only if the stronger verifier catches failures that deterministic checks miss.
## The workload model
The outcome unit is 1,000 pages converted into one fixed JSON schema. Every value below is an assumption. None comes from Vynaris traffic or customer data.
| Assumption | Value | Why it exists |
| --- | --- | --- |
| Pages | 1,000 | Outcome unit |
| Raw HTML per page | 25,000 tokens | DOM, scripts, styles, navigation and content |
| Clean content per page | 6,000 tokens | Main text plus useful labels after deterministic stripping |
| Extraction output | 300 tokens | One compact JSON object |
| Verification sample | 15% of pages | Second pass over 150 extracted objects |
| Verification output | 80 tokens | Pass/fail plus field-level issues |
| Expected schema-drift retry | 5% of pages | Amortized reruns after selectors or schema rules change |
| Batch mode | Not assumed | Keeps provider rows comparable |
The public demand receipt is the Context.dev launch thread. It describes URL-to-Markdown, rendered HTML and JSON-schema extraction. The discussion also exposes the hard part: clean content is easy to demo, while production reliability across page shapes takes maintenance. We use that as a workload signal, not a price source.
This playbook differs from our [invoice extraction cost model](https://vynaris.com/blog/llm-document-extraction-cost-per-1000-invoices-playbook). An invoice is already a compact document and its main cost floor is human exception review. A web page arrives wrapped in disposable markup. Here the distinct lever is deterministic input reduction before [inference](https://vynaris.com/glossary/category/cost-and-finops#llm-inference-cost), followed by drift detection.
## Verdict: model cost per 1,000 pages
| Model | Raw HTML pipeline | Clean-content pipeline | Cleanup saving |
| --- | --- | --- | --- |
| [deepseek-v4-flash](https://vynaris.com/models#deepseek-v4-flash) | $4.2979 | $1.1059 | 74.3% |
| [GPT-5.6 Luna](https://vynaris.com/models#gpt-5-6-luna) | $6.4014 | $1.8414 | 71.2% |
| [Gemini 3.5 Flash-Lite](https://vynaris.com/models#gemini-3-5-flash-lite) | $9.8310 | $2.9910 | 69.6% |
| [Claude Haiku 4.5](https://vynaris.com/models#claude-haiku-4-5) | $31.6800 | $8.8800 | 72.0% |
| [Claude Sonnet 5](https://vynaris.com/models#claude-sonnet-5) (intro) | $63.3600 | $17.7600 | 72.0% |
Prices are standard per-1M-token rates. DeepSeek is $0.14 input and $0.28 output. Luna is $0.20/$1.20. Flash-Lite is $0.30/$2.50. Haiku is $1/$5. Sonnet 5 is $2/$10; Anthropic canceled the scheduled 2026-09-01 increase. Updated 2026-08-14.
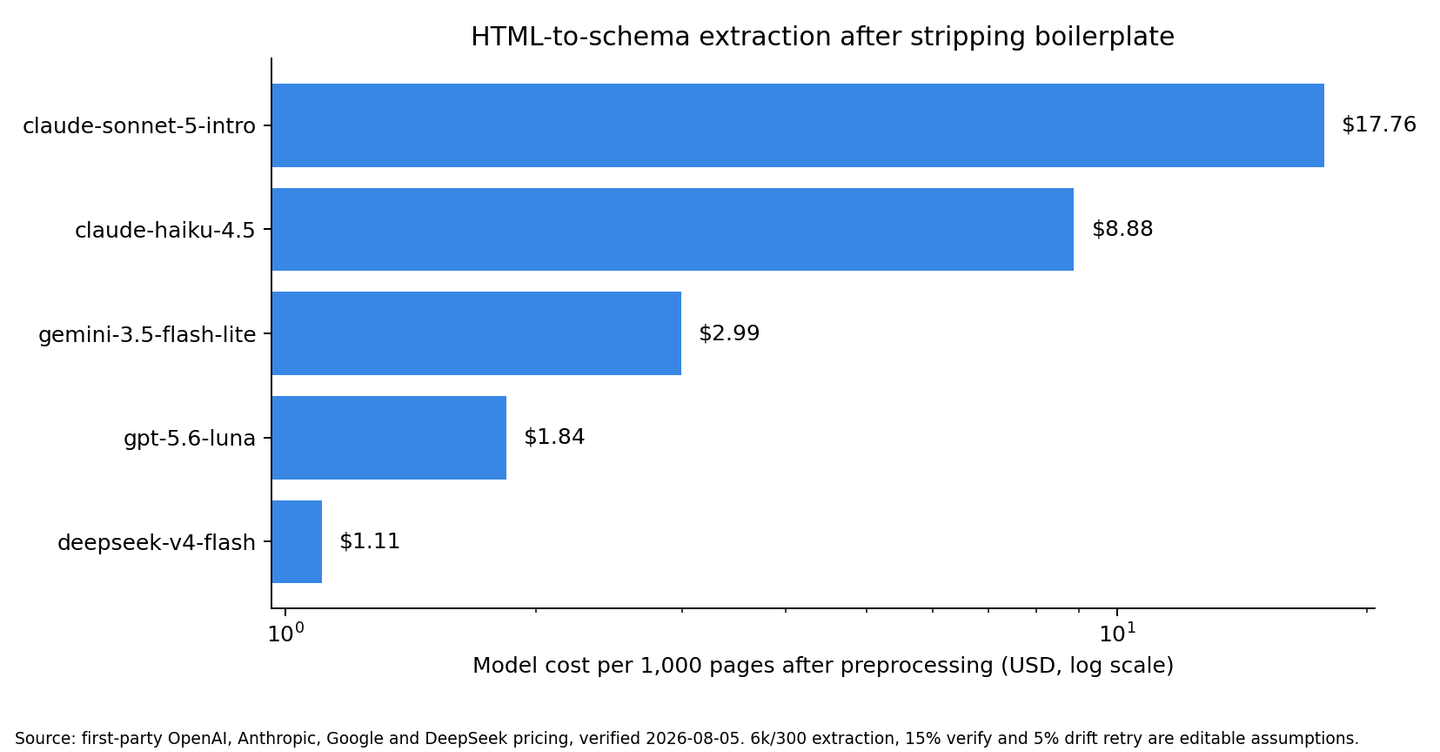
*Model cost per 1,000 pages after stripping HTML boilerplate. Source: first-party provider pricing verified 2026-08-05. The 6k/300 extraction, 15% verify and 5% drift retry are editable assumptions.*
## The arithmetic behind $1.11
The clean DeepSeek pipeline has three lines.
```
Base extraction:
1,000 x (6,000 x $0.14 + 300 x $0.28) / 1M = $0.92400
15% verification:
150 x (6,300 x $0.14 + 80 x $0.28) / 1M = $0.13566
5% schema-drift retry:
50 x (6,000 x $0.14 + 300 x $0.28) / 1M = $0.04620
Total = $0.92400 + $0.13566 + $0.04620 = $1.10586
```
The 6,300 verification input contains the 6,000 clean page tokens plus the 300-token extracted object. Verification emits only a short verdict.
Across the whole batch, raw HTML sends 30.045M input tokens. Cleanup reduces that to 7.245M, a 75.9% cut. Output stays fixed at 327,000 tokens. That is why dollar savings land slightly below the input reduction: cleanup cannot shrink the JSON output.
Use [the cost calculator](https://vynaris.com/calculator?in=7245&out=327) with the normalized per-page totals, then multiply by 1,000. Keep preprocessing outside the model bill so you can see whether it is actually earning its CPU and engineering cost.
## Preprocessing beats prompt tricks on unique page content
[Prompt caching](https://vynaris.com/glossary/category/inference-and-serving#prompt-caching) helps repeated prefixes. It does not make 19,000 tokens of page-specific navigation and script blobs disappear. Those tokens differ by URL, build hash, tracking configuration and personalization. Treating them as cacheable is optimistic accounting.
The preprocessing sequence is deliberately boring:
1. Remove `script`, `style`, `noscript`, SVG and hidden nodes.
2. Drop repeated header, footer, navigation and cookie-banner blocks.
3. Prefer `main`, `article` and labeled content regions.
4. Preserve tables, headings, links and field labels that affect the schema.
5. Enforce a token ceiling before the model call.
Do not ask the model to clean HTML and extract JSON in one expensive pass. Deterministic cleanup is cheaper, testable and stable. The model should spend tokens on semantic mapping, not on recognizing that a minified analytics bundle is irrelevant.
Our [extraction workhorse comparison](https://vynaris.com/blog/extraction-workhorse-gpt54mini-haiku45-deepseekv4flash) shows the model-only price spread. This playbook adds the upstream lever that changes every model's denominator.
## Schema drift is an expected retry line
A pipeline that works today can fail when a site renames a plan card, moves prices into a modal or swaps server-rendered content for client-side data. We model drift as a 5% expected rerun across the batch. That is not a claim that 5% of pages fail. It is an editable budget allowance.
| Expected drift retry | DeepSeek clean | Sonnet 5 clean |
| --- | --- | --- |
| 0% | $1.0597 | $17.0100 |
| 5% | $1.1059 | $17.7600 |
| 10% | $1.1521 | $18.5100 |
| 20% | $1.2445 | $20.0100 |
| 50% | $1.5217 | $24.5100 |
The model bill rises gently because inference is cheap. The operational risk does not. A 50% rerun may mean half your records were stale until detection fired. Track [structured outputs](https://vynaris.com/glossary/category/agents-and-harnesses#structured-outputs) by schema version and source template, not only by provider request ID.
Use deterministic schema validation before a second LLM call. Required fields, types, enums, URL formats and cross-field checks catch many failures for zero token cost. An LLM verifier belongs on ambiguous semantics, not malformed JSON.
## Where routing changes the unit economics
One practical split runs base extraction and drift retries on DeepSeek, then sends the 15% verification sample to Sonnet 5.
| Component | Model | Cost |
| --- | --- | --- |
| 1,000 base extractions | deepseek-v4-flash | $0.9240 |
| 150 verification calls | Claude Sonnet 5 | $2.0100 |
| 50 expected drift retries | deepseek-v4-flash | $0.0462 |
| Routed total | | $2.9802 |
The routed pipeline is 83.2% below all-Sonnet at $17.76. It is also 2.7x the all-DeepSeek line. That extra $1.8743 buys a stronger semantic checker, not guaranteed accuracy.
[Model routing](https://vynaris.com/glossary/category/routing-and-cost#model-routing) makes sense when your validator can identify a hard tail before escalation. Useful signals include missing required fields, disagreement across two parses, totals that fail a checksum and a new page-template fingerprint. A confidence score with no calibration is not a gate. It is another guess with a bill.
## Build notes specific to web extraction
- Store the raw response hash, cleaned text hash, schema version and extracted object together. That gives [LLM cost attribution](https://vynaris.com/glossary/category/cost-and-finops#llm-cost-attribution) a stable unit and makes drift reruns auditable.
- Separate browser rendering from model extraction. A failed render should not consume model tokens.
- Cache fetched pages and respect site policies. Repeated crawling can cost more in browsers and proxies than inference.
- Keep one golden-page set per template. Run it before changing cleanup rules or model versions.
- Version the schema. A field rename without a version bump looks like model failure downstream.
- Cap input after cleanup. One infinite-scroll page should not set the batch's spend profile.
### Keep browser and cleanup costs beside the model line
The token bill is only one component. JavaScript rendering consumes browser memory and CPU. Residential proxies, retries, storage and anti-bot handling can exceed inference. Price those services as separate units per fetched page. Then add the model line only after a page reaches clean text.
That separation matters when comparing architectures. A cheaper model does nothing for a renderer that opens every page twice. Better boilerplate removal saves model input, but a complex readability pipeline can add maintenance time. Track fetch success, render success, cleanup success, schema validity and semantic accuracy as separate stages. Each stage should have its own failure code and cost owner.
The payoff is operational clarity. When total cost rises, you can see whether the cause is browser retries, longer cleaned pages, more verification calls or a provider price change. One blended “extraction cost” metric hides all four and invites the wrong fix.
The [structured-output overhead analysis](https://vynaris.com/blog/structured-output-json-tool-call-token-overhead-cost) is the next check if your schema instructions are large. Here they are included inside the 6,000-token clean input assumption.
## When this workload does not need a router
Skip routing when a cheap model clears your golden-page set and deterministic checks catch the remaining failures. At $1.11 per 1,000 pages, optimizing the inference line further is theatre.
Also skip the LLM entirely when CSS selectors, JSON-LD or a stable first-party API already expose the fields. A deterministic parser is faster and easier to regression-test. The honest tradeoff is maintenance: selectors break on layout changes, while an LLM tolerates more presentation drift. Use the simplest parser that survives your actual template churn.
## FAQ
**What does LLM web-data extraction cost per 1,000 pages?** On this 6,000-input / 300-output workload with 15% verification and 5% expected drift retries, $1.1059 on deepseek-v4-flash to $17.7600 on Claude Sonnet 5.
**Why strip HTML before sending it to the model?** Cleanup removes 22.8M of 30.045M batch input tokens in this model. That cuts input 75.9% and dollars 69.6% to 74.3%, without changing output length.
**Does prompt caching remove the HTML boilerplate cost?** Usually not. Page chrome contains URL-specific and build-specific content, so much of it is not a stable shared prefix. Deterministic stripping removes it reliably.
**When should a stronger model verify extraction?** When cheap deterministic checks expose an ambiguous hard tail and the cost of a wrong field exceeds the escalation premium. Route the flagged 15%, not every page.
**When should I avoid an LLM?** When a stable API, JSON-LD block or selector returns the exact field. Paying a model to parse deterministic structure adds latency and failure modes.
## Sources
- [OpenAI API pricing](https://developers.openai.com/api/docs/pricing), captured 2026-08-05: GPT-5.6 Luna $0.20/$1.20 standard.
- [Anthropic API pricing](https://platform.claude.com/docs/en/about-claude/pricing), re-verified 2026-08-14: Haiku 4.5 $1/$5; Sonnet 5 $2/$10 standard.
- [Gemini API pricing](https://ai.google.dev/gemini-api/docs/pricing), captured 2026-08-05: Gemini 3.5 Flash-Lite $0.30/$2.50 standard.
- [DeepSeek API pricing](https://api-docs.deepseek.com/quick_start/pricing), captured 2026-08-05: deepseek-v4-flash $0.14 cache miss / $0.28 output.
- [Launch HN: Context.dev](https://news.ycombinator.com/item?id=48847562), captured 2026-08-05: public evidence for URL-to-clean-content and JSON-schema extraction; 119 points and 86 comments.
All page counts, token counts, sample rates and retry rates are shown assumptions. Replace them before using the totals in a budget.
## About the author
[Dhrumil Barot](https://vynaris.com/about#founder), Founder. Dhrumil is an AI inference and LLM infrastructure expert. Dhrumil built Vynaris to make model access, routing and pricing simple and transparent for developers. [LinkedIn](https://www.linkedin.com/in/bdhrumil) · [X](https://x.com/fyidhrumil)